<- Back
Comments (107)
- variagaNot making any claims about a specific model's capabilities, but all these "can interpret model weights" posts brings to mind the line in Shakespeare's Henry IVGLENDOWE: I can call spirits from the vasty deep.HOTSPUR: Why, so can I, or so can any man, but will they come when you do call for them?I can interpret weights too, but will that interpretation be correct?
- zkmonQwen-3.8-27B - the best thing that happened in AI so far.This thing can accomplish the same results as the frontier models do, if you are willing to play a role of an higher level architect or decision maker. Guide it a bit here and there like a tech lead and you get everything done.The money you pay for frontier models is exactly for outsourcing that high level direction work to agents.
- athrowaway3zHopefully we get a new benchmark: How well can a model tweak a set of weights to produce pelican on a bike?
- data-ottawaPerhaps I’m missing this, but can Qwen 3.8 alter Qwen 3.8 weights?There are a lot of known neurons in the older Qwen models that are long known to induce behaviour changes (see evil Qwen by changing one weight).My question boils down to how much is trained vs being able to actually understand the weights. Presumably a same gen model isn’t trained on any sources dissecting that generation. And how much do longer known conceits like steering vectors, J spaces, LoRAs play into this?This doesn’t explain the game training cases, which are very impressive to me.
- layer8> I’m not ready to declare that the age of source code is over and our future involves incomprehensible machines editing their own model weights in incomprehensible ways.That sounds a bit like biology; maybe AI will become like that.
- qwe-asklWhy would it not be able to interpret model weights in such a constructed prompt with tons of information and leading questions?I hope you at least switched off all network access, in case the model cheats and reads HN from yesterday.
- NitpickLawyerSimon, could you try reproducing Experiment 5 from the blog post, if you have a chance? Apparently this person tried [1] with API models and only the latest models can do the impressive 10-20x vs. PPO baseline.[1] - https://nitter.netbub.com/AlexKrentsel/status/21173766837246...
- stanskiSemi-related question I was wondering about recently - how is it that Alibaba has a better consumer-friendly open model (for coding anyway) than research-leading companies like Google?
- orsornaWhy would you want to change weights directly versus running through a new training cycle? For example, I have collected a bunch of data I would like to train weights that I use local inference for. I figured a LoRa would be the way to go, perhaps be more cost effective and generalized too.
- boznzAll the talk is of the improvement in a capability, but has there been any study on What are these changes are breaking ?
- tarrudaI wonder how far this can be taken. Could Qwen 3.8 can interpret and make improvements to Qwen 3.5 0.8B weights, or even its own weights?
- K0baltHmm. Possibilities for RSI? Big MOE does brain surgery on and invents new expert modules in its catalog?
- sagexIsn't the network too shallow to be challenging to decode? One can easily produce few layer network to solve specific goal with construction techniques, so not a surprising result in my view.
- xlaynBut that's obvious... Astra is Qwen, if Astra can is because Qwen can....
- necovekI am surprised nobody caught on "paper shaped" for blog post: I chuckled!
- causalNow how long until Anthropic forbids weight space editing too?
- wg0Off topic - anyone had the occasion to work with IBM Watson?
- gabrielcsapoThe question is can a 4b or smaller improve a 0.5b llm, or would it just get caught in a loop
- devinpraterStill amazing to me that a model that good, Qwen3.8:27b, runs on a laptop.
- bsiverlyWasn’t this one of the main marketing points for the Inkling model as well?
- AlexCoventryI wonder if Qwen releases are deliberately nerfed for some reason. It's not the first time an easy reasoning performance win has been found for one.https://arxiv.org/abs/2506.10947
- tiborsaas> It’s a cool paper, but some of the wider commentary I’ve seen around it does not feel justified. I’m not ready to declare that the age of source code is over and our future involves incomprehensible machines editing their own model weights in incomprehensible ways.The age of source code is definitely not going to end anytime soon if ever. But the future will involve incomprehensible machines editing other models in a "fairly certain" way, but we are going to need a lot of tooling to keep up with the process and not just take the model updates as "trust me bro".
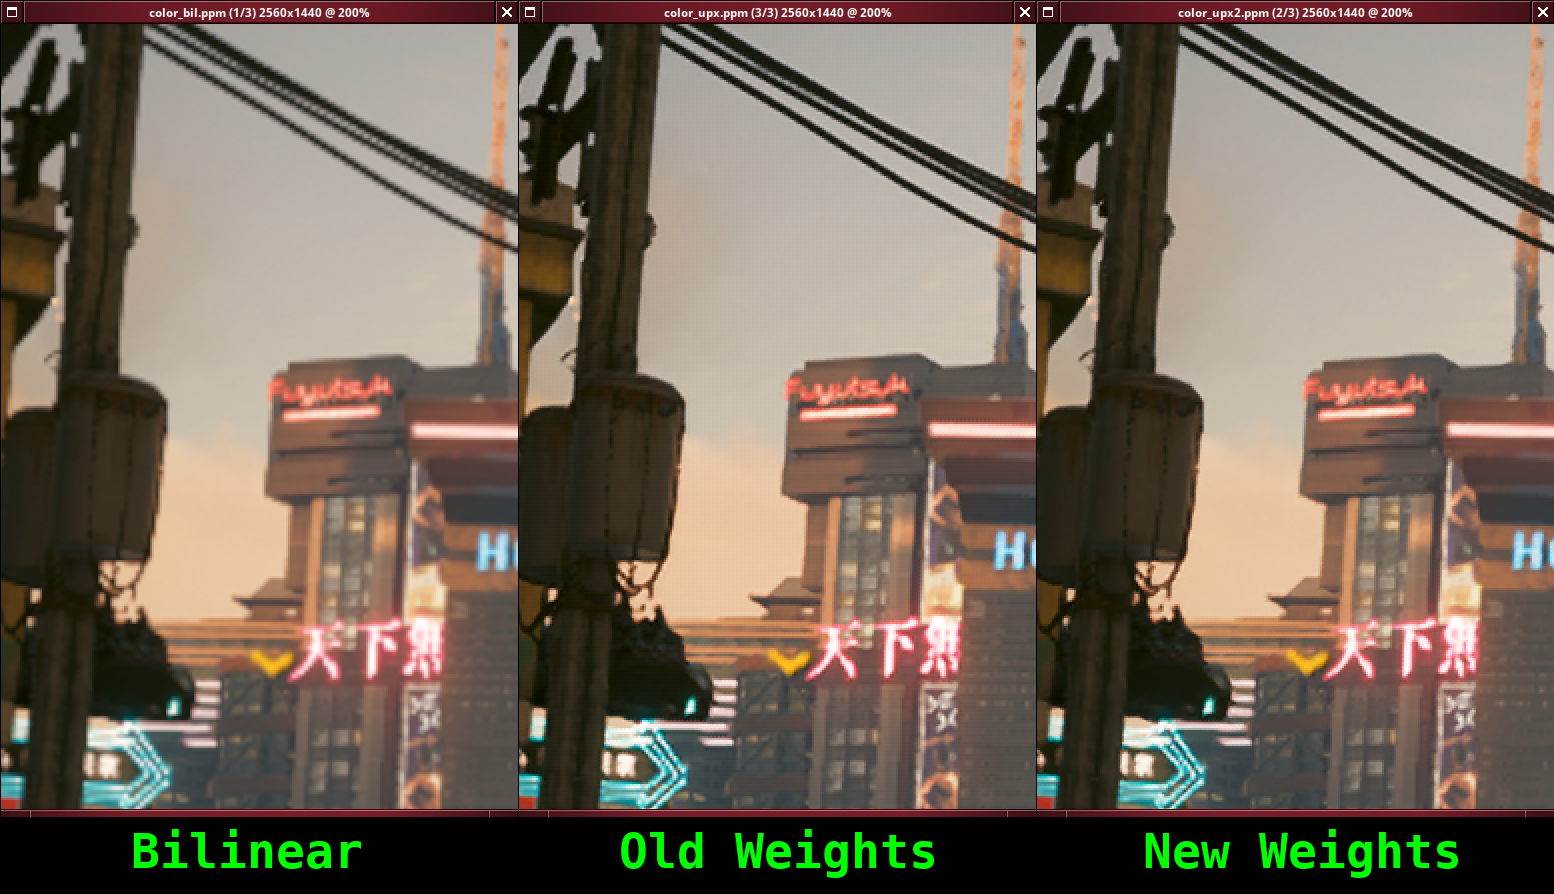
- badsectoraculaI did exactly the same thing with Qwen 3.8 27B but i also asked it something else: a couple years ago i wrote a simple upscaler[0] when i was learning about neural networks. The network is dead simple: it takes a 25 inputs for a 5x5 grid around a pixel and outputs the 2x2 pixel grid that the input pixel should be replaced for a (width2)x(height2) upscale. I trained it on a bunch of random images (in hindsight i should have trained it on game screenshots but w/e) and it looked quite nice.So i asked Qwen 3.8 27B two things:1. What it is this network all about? I only gave it the ann.c code that implemented a simple artificial neural network library in C and the setup code that specified the network's shape but not its purpose.Qwen 3.8 27B tried a bunch of stuff, taking the layers one by one, proding numbers through it, etc and finally figured out it is some sort of 5x5 to 2x2 filter, most likely working with pixels (i never mentioned pixels or graphics), though it wasn't certain about the exact purpose. It did rule out a bunch of uses like being a downscaler or classifier, from its behavior.2. After i revealed what it was, i asked it if it can improve it but keep it 100% compatible with the existing program that used the weights file. And sure enough, it did improve it. I gave it the original training C code and dataset. It made a few experiments (and wrote its own training C code because it found mine too slow :-P) and ended up improving the weights. The difference[1] is small, but it basically eliminated some small noise that was always there and made some transitions less "halo-y". Of course for the purpose i wanted it (use it to upscale games in realtime) it isn't that great (too heavy) but it was learning material anyway. Though one bonus thing i noticed is that it upscales my random doodles much better than any Krita filter[2] :-P.The above isn't Qwen 3.8 27B observing the weights directly and making sense out of them (ok actually it did seem to make some sense of the weights in the "#1" but i didn't dump the entire network to it - though thinking about it, it is only around 16384 floats so it might work). It just used a bunch of scripts it wrote in Python (and later C) but i still found it interesting to watch it go at it.[0] https://mastodon.gamedev.place/@badsector/113765818432603610[1] http://runtimeterror.com/pages/iv/images/a3d94ea369ff95ecf05...[2] http://runtimeterror.com/pages/iv/images/4e29d027a8aa6e89db5...
- alexcarterhqhave you tried it on wspbench?
- mccoybWhy do people keep calling this a paper?It's a blog post which received feedback from collaborators.It hasn't gone through the academic paper lifecycle ... the authors themselves refer to it as a post and as preliminary.I feel like I'm taking crazy pills, but can we be precise when talking about work of this form? It started with referring to arXiv pre-prints as papers, and now we're at blog posts with an academic template as papers.A paper is a fucking paper: something which has been vetted by the scientific community, with at least some form (often, a few rounds) of anonymous review from people outside your circle of collaboratorsThis is not there yet, and clearly so due to the various feedback from people (including the two pushback posts on HN) critiquing the lack of discussion about the existence of these techniques in mech interp, etc?
- m3kw9i don't get his example, he had a simple model that only plays pong and Qwen can tell by just looking at the weights?
- 0xbadcafebeeIt literally just did math on some numbers based on a set of rules provided in the prompt in order to sketch a visual of a game. It didn't "interpret model weights" any more than an MP3 player "interprets physics of electromagnetic waves". The LLM built its own decoder on the fly for the games... which is what it's doing when you ask it to write code, calculate math, estimate the structural load bearing of a beam, etc.
- notpublic[flagged]